Бесплатно
Исследования и данные
LLM Wiki Compiler
Compile documents, research papers, and notes into a persistent knowledge wiki with source citations and reusable context retrieval.
2,3 тыс.Звёзды240Форки
Последний push репозитория
Atomic Strata
Авторские процессы для сайтов, изображений, презентаций и анимации.
Compile documents, research papers, and notes into a persistent knowledge wiki with source citations and reusable context retrieval.
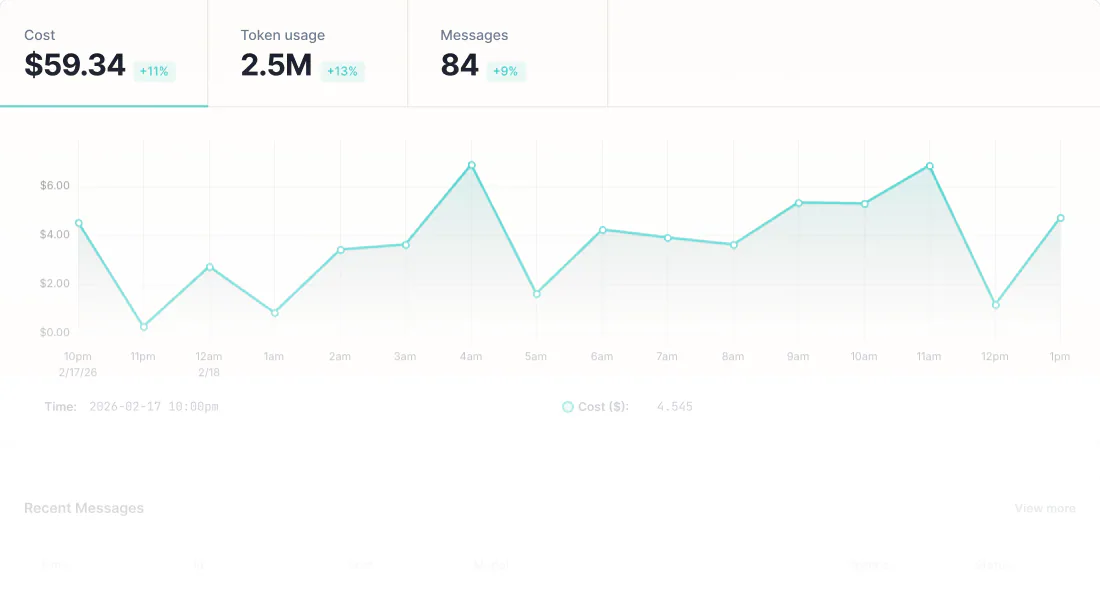
Operate Manifest model routing, application keys, request diagnostics, and LLM cost controls.
Find free LLM API options and follow provider-specific key and endpoint setup instructions.
ai-agents skill for Claude AI. Grade A. Coaches a language learner with a CEFR-targeted plan built on comprehensible input, spaced repetition, and early speaking practice, including daily minimums, a session template, and a weekly schedule. Use when someone says "help me learn Spanish", "I keep forgetting vocabulary", "how do I get from A2 to B1", or "design my daily language routine". Do NOT use for general exam or academic study techniques - use study-system instead.
ai-agents skill for Claude AI. Grade A. General Blender workflow skill for AI agents working with .blend, .fbx, .obj, .glb, glTF, materials, scene inspection, bpy automation, headless Blender batch runs, export/reimport validation, previews, and optional Blender MCP control. Use when a task asks to open, inspect, create, automate, convert, optimize, render, or verify Blender or 3D asset files in a user-agnostic way.
Build, redesign or audit websites with a clear visual direction, 48 themes or custom styling, and local UI checks for Claude Code, Codex, Cursor and OpenCode.
Identify and label application LLM workflows for Caveman Cloud cost attribution.
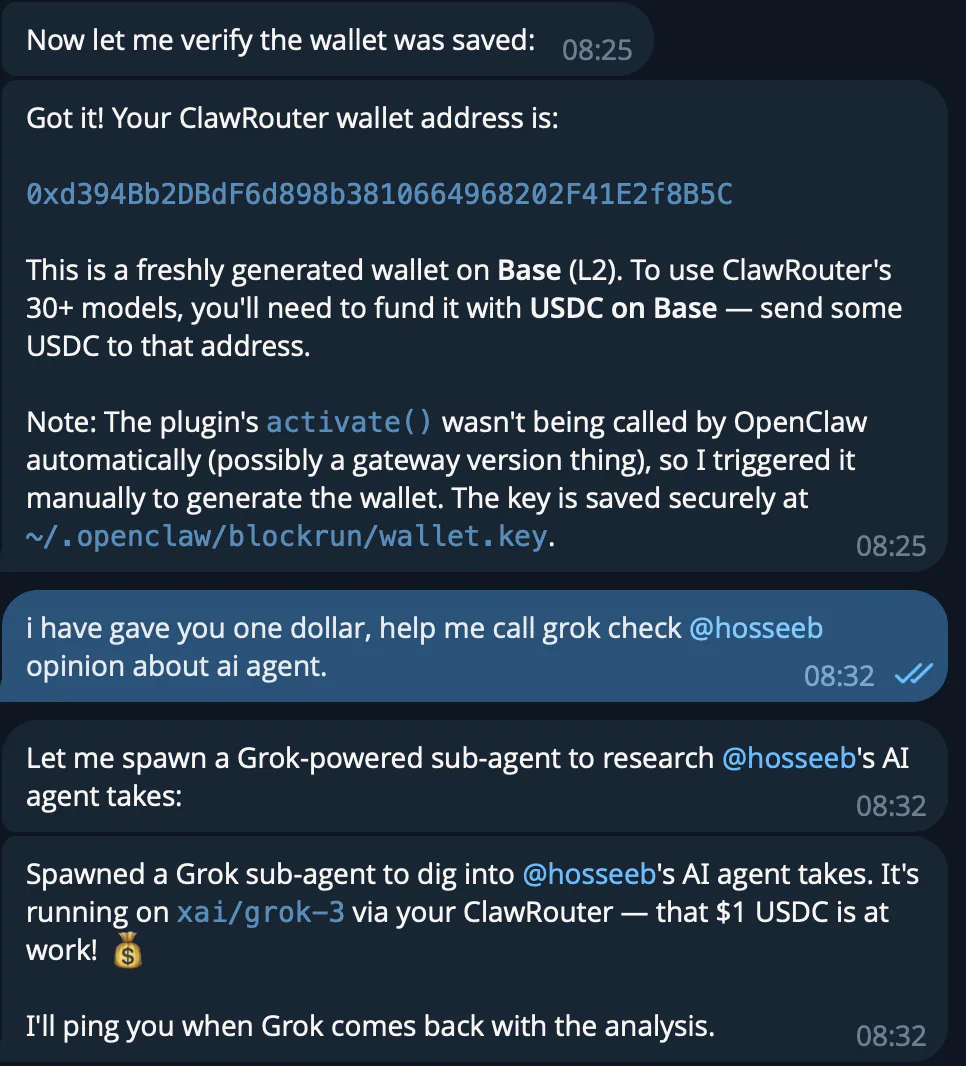
Route model requests through the BlockRun hosted gateway and use the associated agent tools.
Connect an application’s LLM calls to the Caveman Cloud gateway for measurement.
Practical workflows for assessing and improving product-specific LLM evaluations.
Audit an LLM evaluation pipeline for missing error analysis, unvalidated judges, data leakage and stale checks.
Run a managed pentest of a web app, API, repository, or local workspace on the app.strix.ai platform with the `strix cloud` CLI or REST API — no local Docker or LLM key needed.
Field-tested methodology and concrete recipes for training and operating large-scale LLM/VLM/multi-modal models end to end - choosing and benchmarking accelerators, storage and network; SLURM/Kubernetes orchestration; maximizing training throughput and fitting models in memory; diagnosing and surviving training instabilities, NaN/Inf, and hardware/job failures; checkpointing and fault tolerance; inference…
Небольшая библиотека, созданная с заботой. Скоро появятся новые навыки.