Pricing not specified
Testing & security
Rapid MLX Performance Workflow
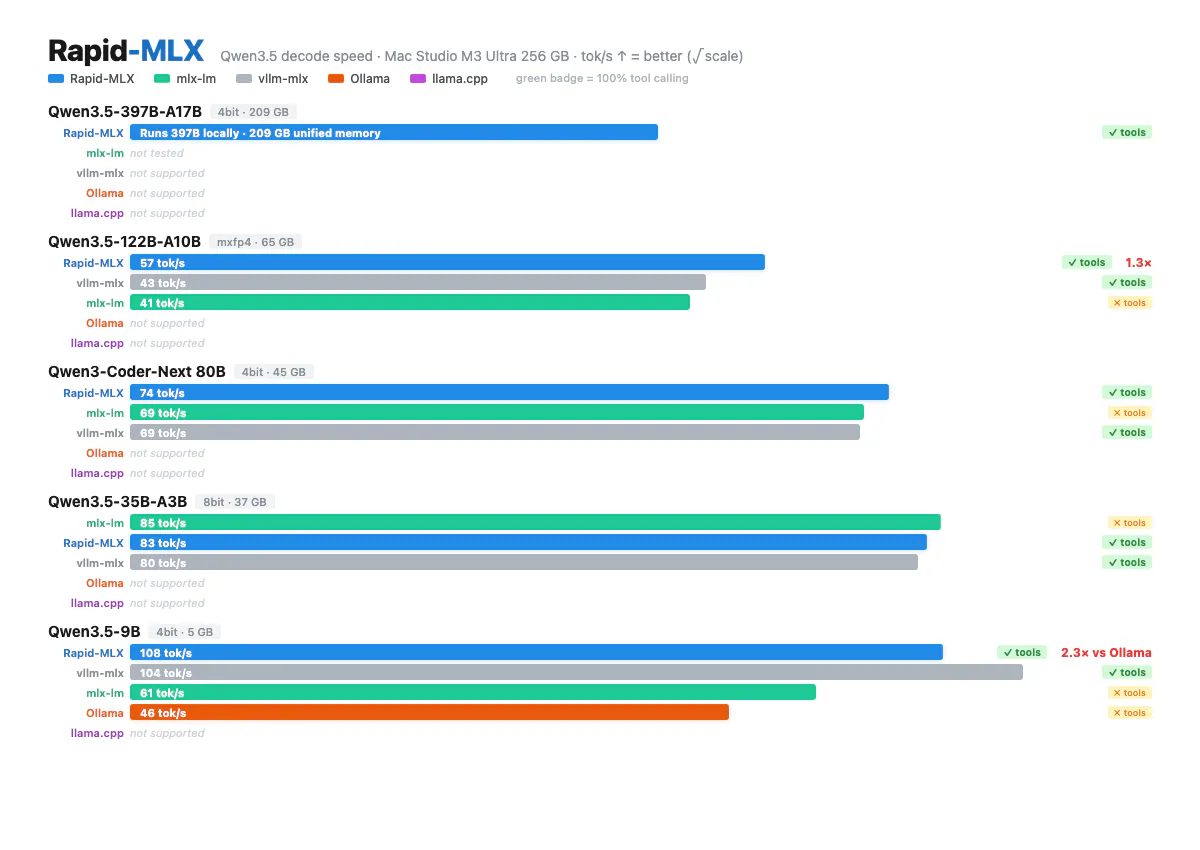
Investigate Rapid MLX performance, prototype changes, benchmark results, and prepare reviewed improvements.
4KStars432Forks
Repository last pushed
raullenchai
Original workflows for websites, images, presentations, and everything in motion.
Investigate Rapid MLX performance, prototype changes, benchmark results, and prepare reviewed improvements.
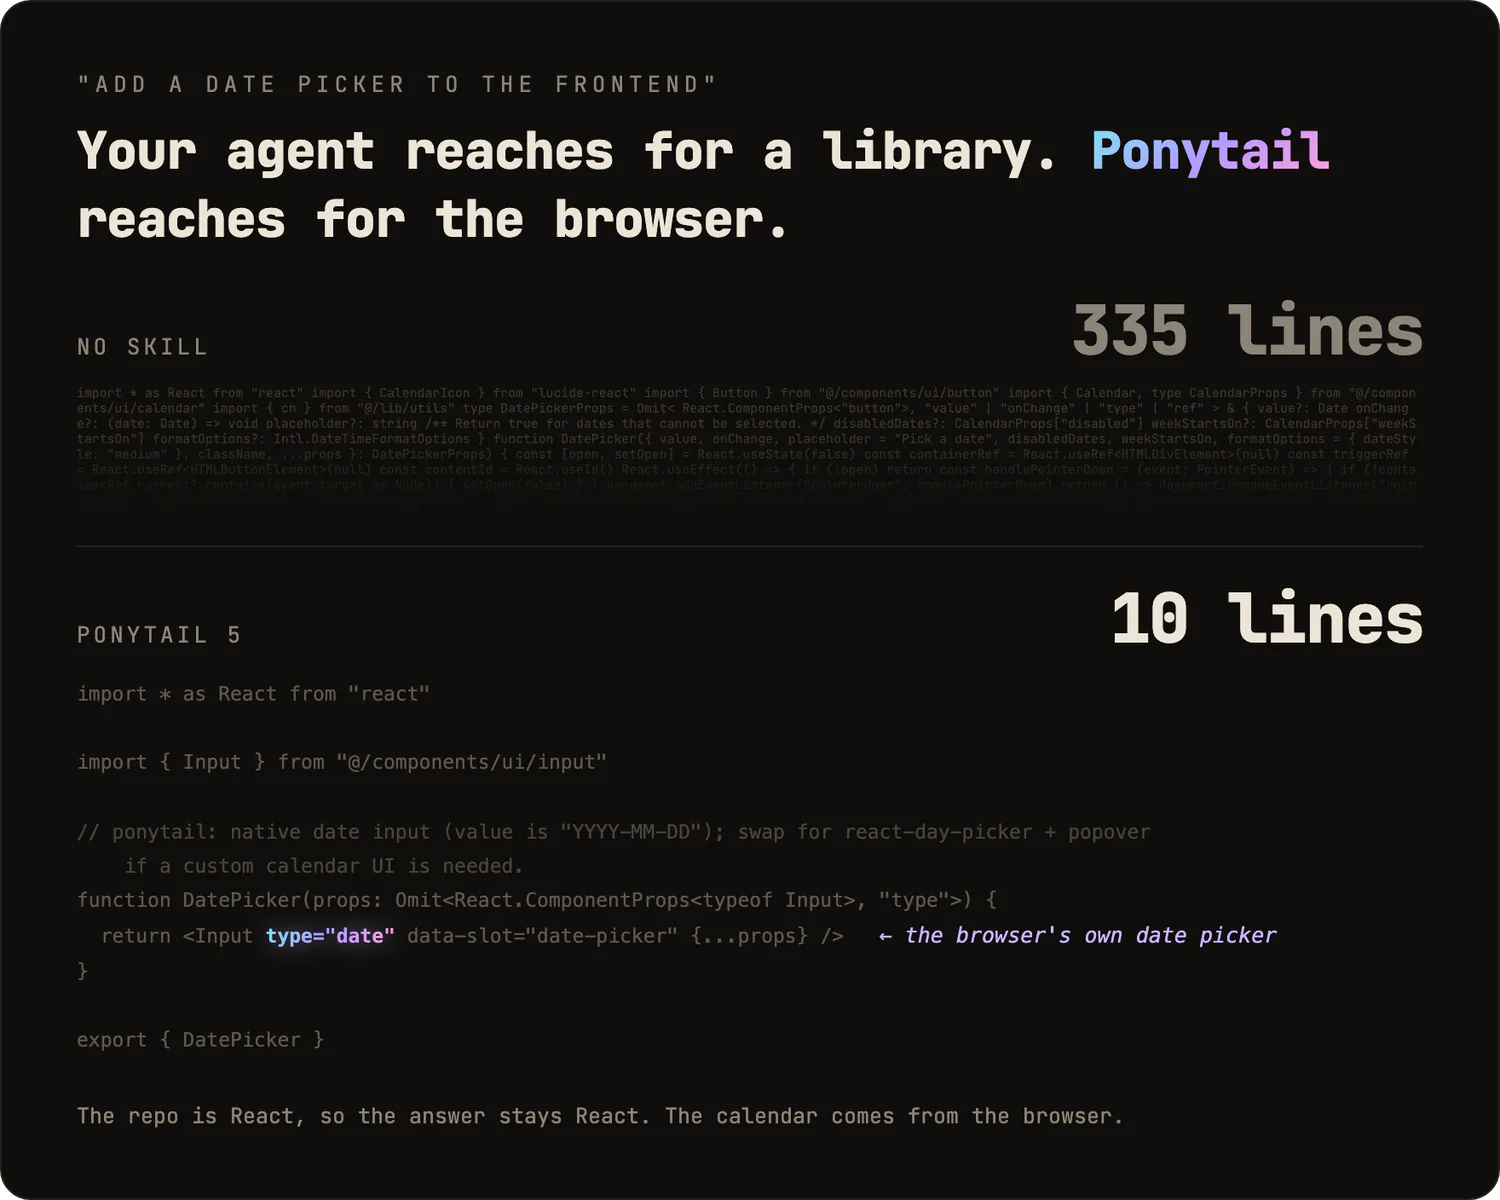
Display Ponytail’s recorded benchmark results for code size, cost and execution speed.
Field-tested methodology and concrete recipes for training and operating large-scale LLM/VLM/multi-modal models end to end - choosing and benchmarking accelerators, storage and network; SLURM/Kubernetes orchestration; maximizing training throughput and fitting models in memory; diagnosing and surviving training instabilities, NaN/Inf, and hardware/job failures; checkpointing and fault tolerance; inference…
Apply practical large-model training and operations guidance, and evaluate GPU cluster performance and readiness.
Evaluates an ML GPU cluster for a cloud trial or acceptance test: environment dump, isolated newest PyTorch, matmul FLOPS (MAMF/MSMF) on every GPU while the others compute, intra-node all-reduce bandwidth and per-call latency of every collective, the same inter-node on every node you were given (omit those sections if there is only one node), fio on local disk and shared FS, dated markdown report.
A small library, made with care. More skills are on the way.