Rebuild scanned Chinese books as structured Word documents using MinerU OCR, title mapping and proofreading against the original pages.
19Stars1Forks
Repository last pushed
These skills help an agent extract text from scans and carry it into another document format. Members cover PDF processing, MinerU, scanned PDF conversion, image-to-PPT work, and vision tools.
8 skillsRebuild scanned Chinese books as structured Word documents using MinerU OCR, title mapping and proofreading against the original pages.

Create and inspect PDFs, extract text and tables, merge pages and process forms or scanned documents.
Parse PDFs, scans and Office files into Markdown with MinerU, with OCR, formula and table extraction, batch processing and optional local parsing.
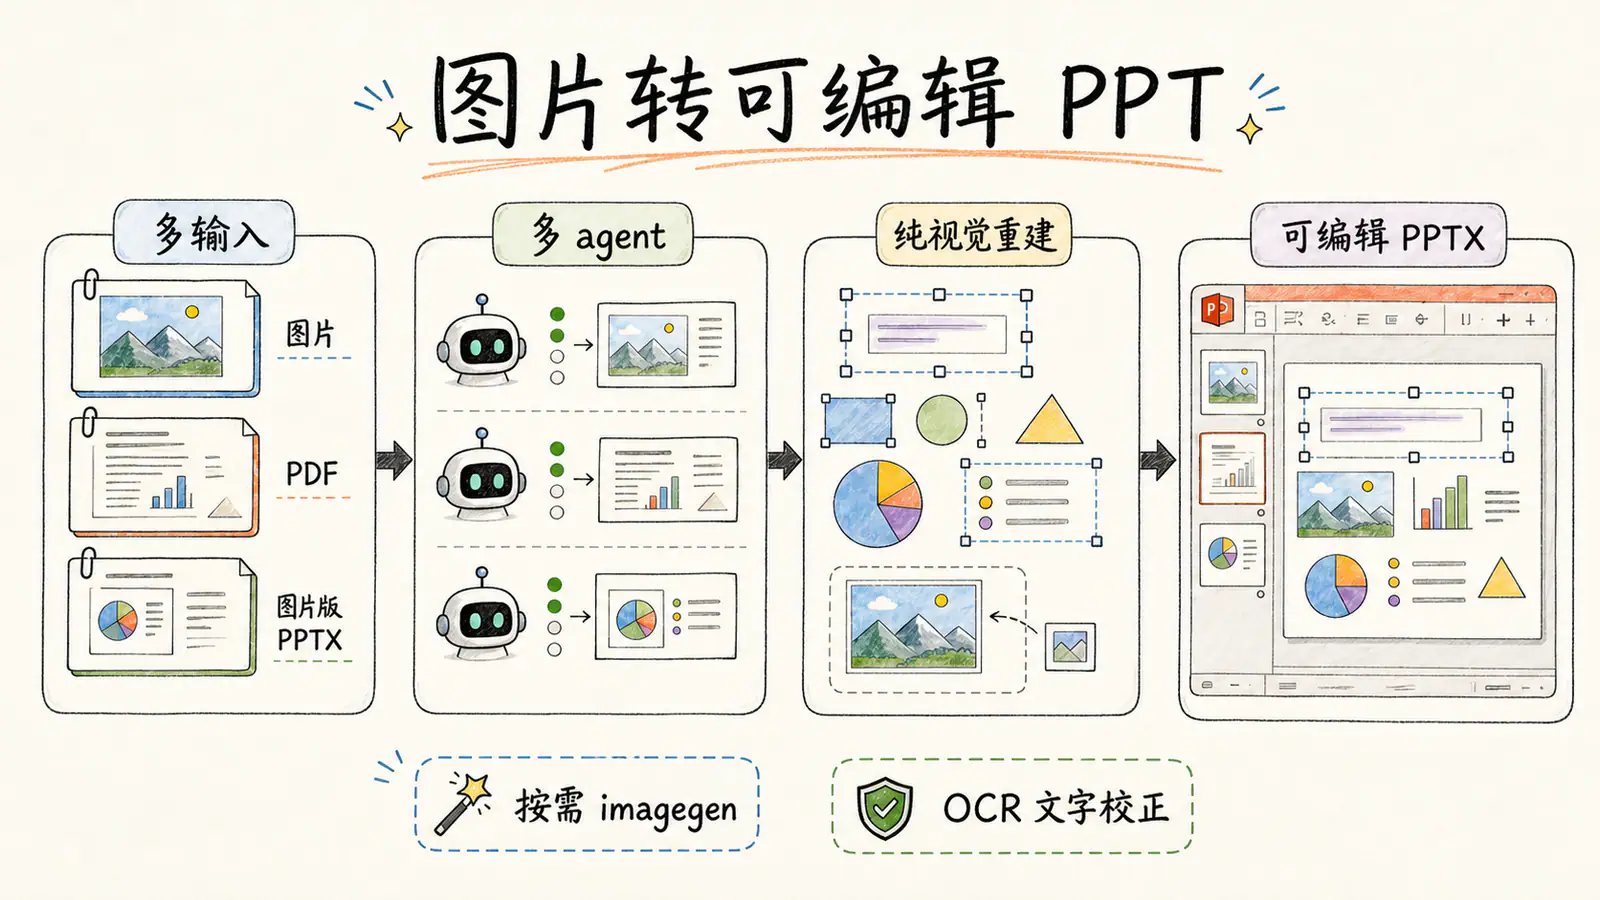
Rebuild slide images, scanned PDFs and image-based PPTX into editable PowerPoint text, tables and shapes, with separate visual assets and validation.

Reconstruct slide images, scanned PDFs and image-only decks as object-level editable PowerPoint, with render comparisons.
Equip text-only agents with image questions, OCR, target localization, cropping, SVG tracing, and screenshot comparison tools.
Parse PDFs, scans and Office documents with OCR, structured extraction and stable page or block citations.
Choose PDF skills for text extraction, page operations, document creation and paper reading. Compare specific workflows, dependencies and useful handoff checks.
Use a document parser when layout matters, a PDF-to-Word workflow for editable output, and a vision skill when the scan contains tables or diagrams.