Rebuild scanned Chinese books as structured Word documents using MinerU OCR, title mapping and proofreading against the original pages.
19Stars1Forks
Repository last pushed
These skills help an agent parse PDFs and scanned pages, run OCR, and convert documents to Word, Markdown, or PowerPoint. Other entries generate React-PDF output and support paper reading or translation.
18 skillsRebuild scanned Chinese books as structured Word documents using MinerU OCR, title mapping and proofreading against the original pages.

Turn a visual philosophy into original poster art and carefully composed PNG or PDF designs.
Fetch web pages and PDFs, then return clean Markdown, summaries, or cited extracts.
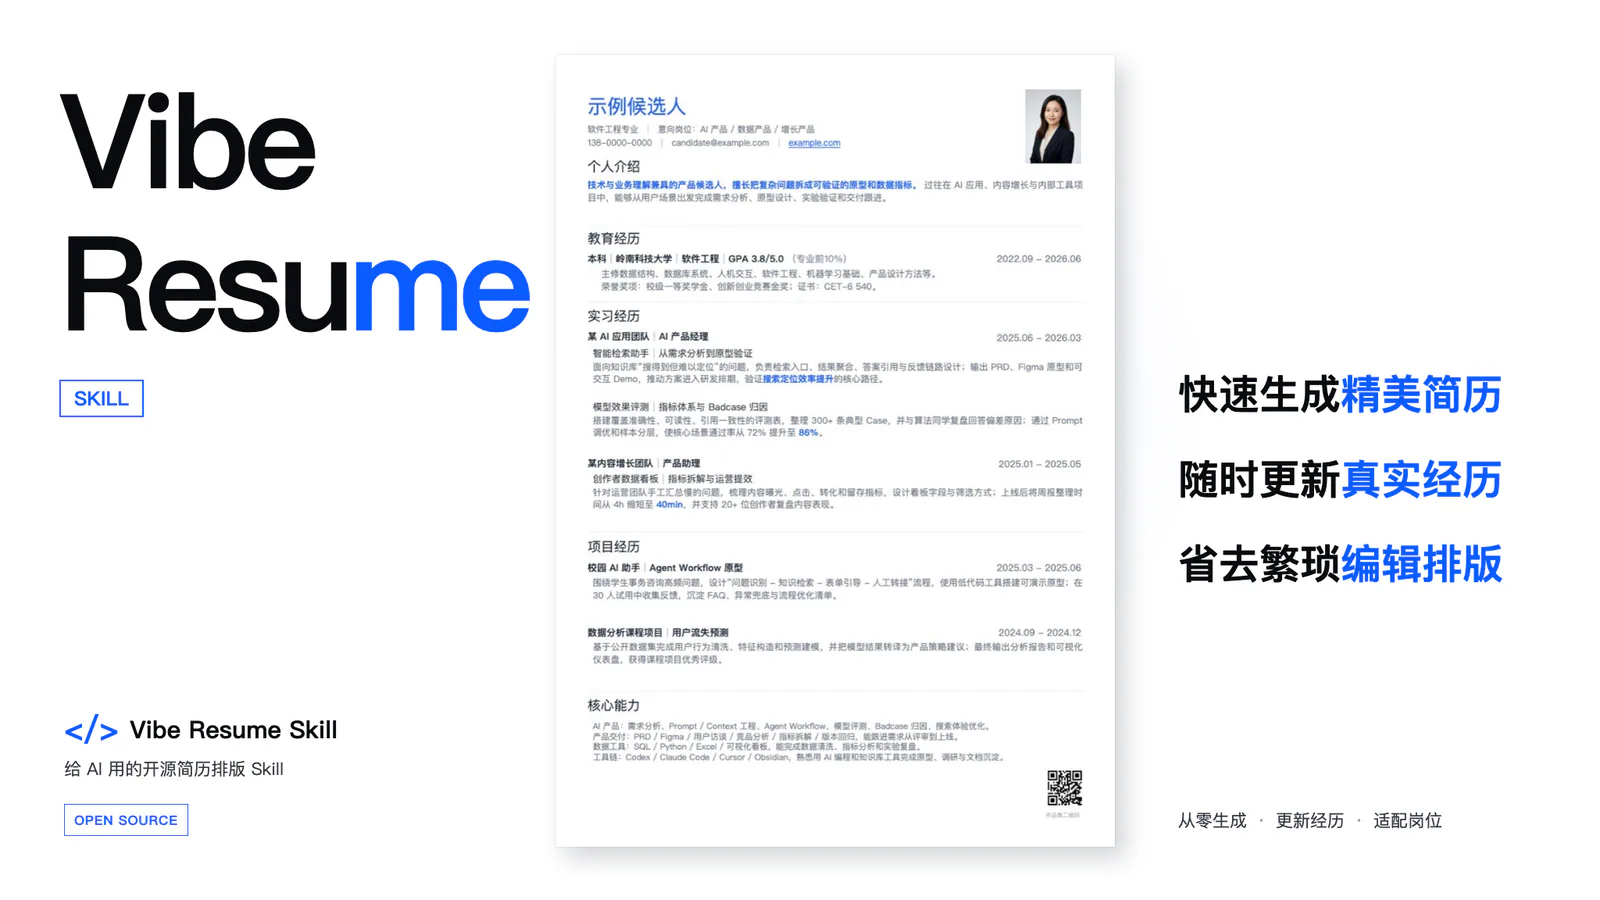
Create and tailor one-page HTML and PDF resumes with 12 templates and a YAML-based workflow. Free for non-commercial use.
Create reports, invoices and other PDFs with React components, reusable layouts, SVG graphics and controlled page breaks.

Create source-linked Chinese-English Markdown paper readers with aligned text, figures, tables and equations.
Use common PDF utilities and Python libraries to read, create, split and merge documents.
Export Markdown files to PDF and other document formats through a local CLI, with Pandoc and Typst used for PDF rendering.
Create and inspect PDFs, extract text and tables, merge pages and process forms or scanned documents.
Generate dimensioned PDF engineering drawings from part geometry, with projected views, hole callouts and a title block.
Parse PDFs, scans and Office files into Markdown with MinerU, with OCR, formula and table extraction, batch processing and optional local parsing.
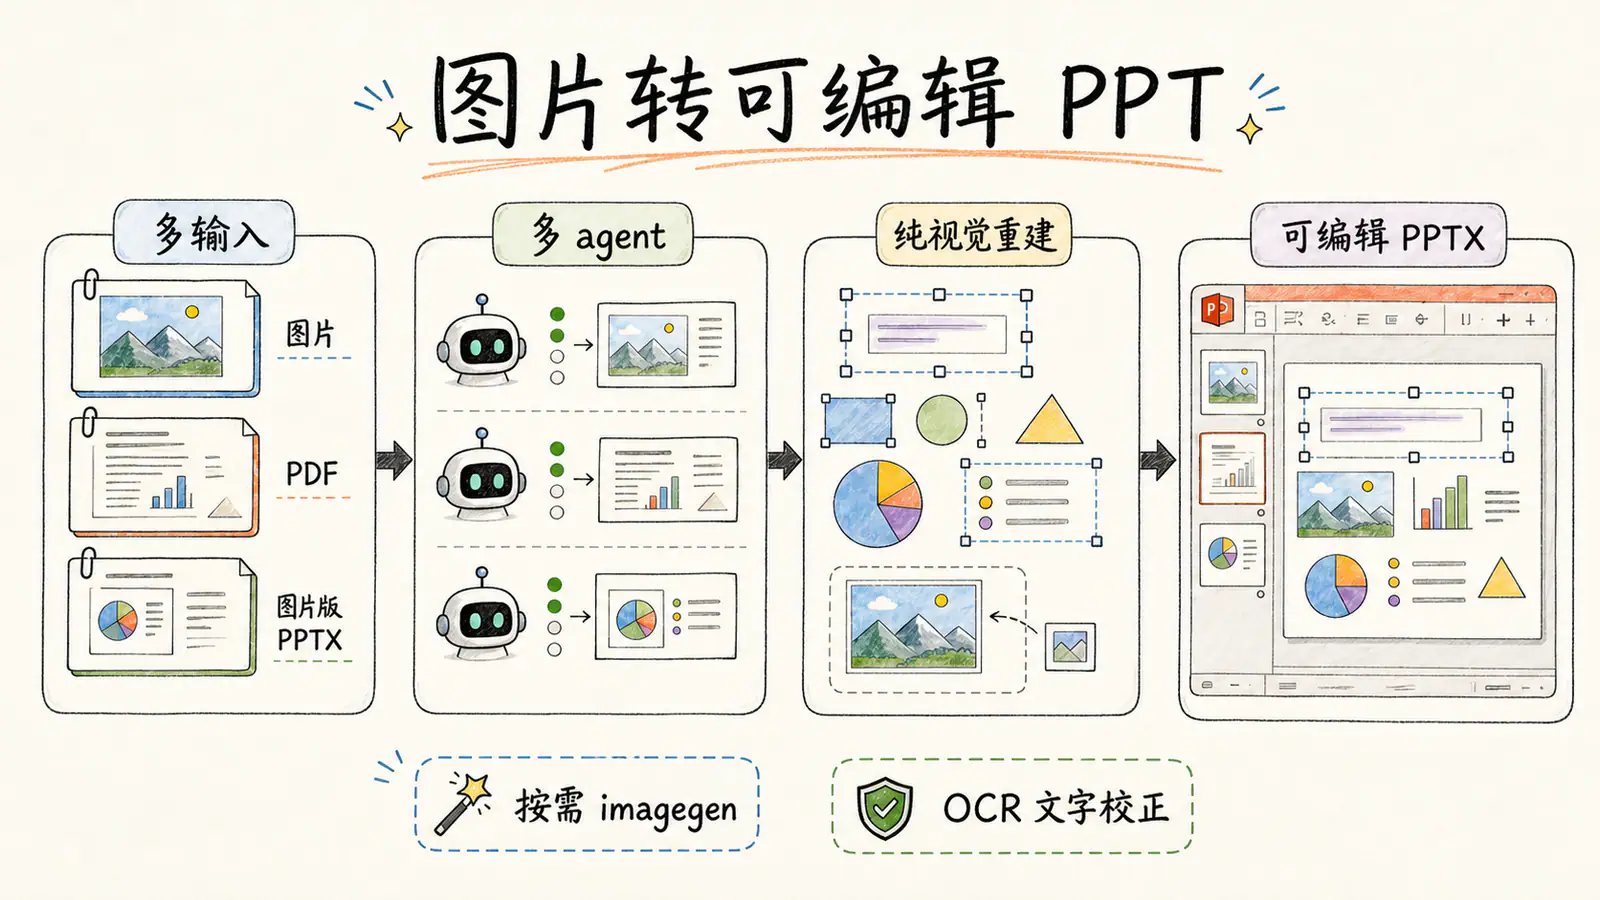
Rebuild slide images, scanned PDFs and image-based PPTX into editable PowerPoint text, tables and shapes, with separate visual assets and validation.
Translate an English paper PDF into a Chinese image-based PDF, preserving page layout and checking each translated page.
Reconstruct slide images, scanned PDFs and image-only decks as object-level editable PowerPoint, with render comparisons.
Equip text-only agents with image questions, OCR, target localization, cropping, SVG tracing, and screenshot comparison tools.
Research a subject across its history and current alternatives, then produce a PDF report.
Parse PDFs, scans and Office documents with OCR, structured extraction and stable page or block citations.
Read, extract (text/tables), create, merge/split/rotate, watermark, encrypt, fill, and render-to-image .pdf files.
Choose PDF skills for text extraction, page operations, document creation and paper reading. Compare specific workflows, dependencies and useful handoff checks.
Choose OCR for scans, parsing or Markdown conversion for extraction, and document or React PDF skills when the result must be a new PDF.